PROJECT 02 • API / CLOUD / BI
Football Analytics Platform
An end-to-end football data platform that ingests API-Football data with Python, models it in Azure SQL and turns it into league, team and player analysis in Power BI.
SCOPE
14 competitions
The reporting dataset covers the top three divisions in England, Spain, France and Germany, plus the top two divisions in Italy.
PIPELINE
API to reporting model
Python ingestion loads API responses into Azure SQL staging before SQL MERGE logic updates fact and dimension tables used by Power BI.
AUTOMATION
Scheduled ingestion
GitHub Actions runs the ingestion outside my local machine, with credentials and configuration managed through environment variables and secrets.
Architecture
Separate ingestion modules handle leagues, teams, fixtures, standings, players, match statistics, events, lineups, injuries and transfers.
Engineering challenge
The API request allowance was not large enough to load every historical league, season and detailed endpoint in a single run. I handled this by batching historical ingestion by league and season while keeping the same pipeline and transformation logic.
Staging tables made it easier to inspect extracted data before updating the reporting model, while SQL upserts kept changing football data current without repeatedly inserting duplicates.
POWER BI DASHBOARD
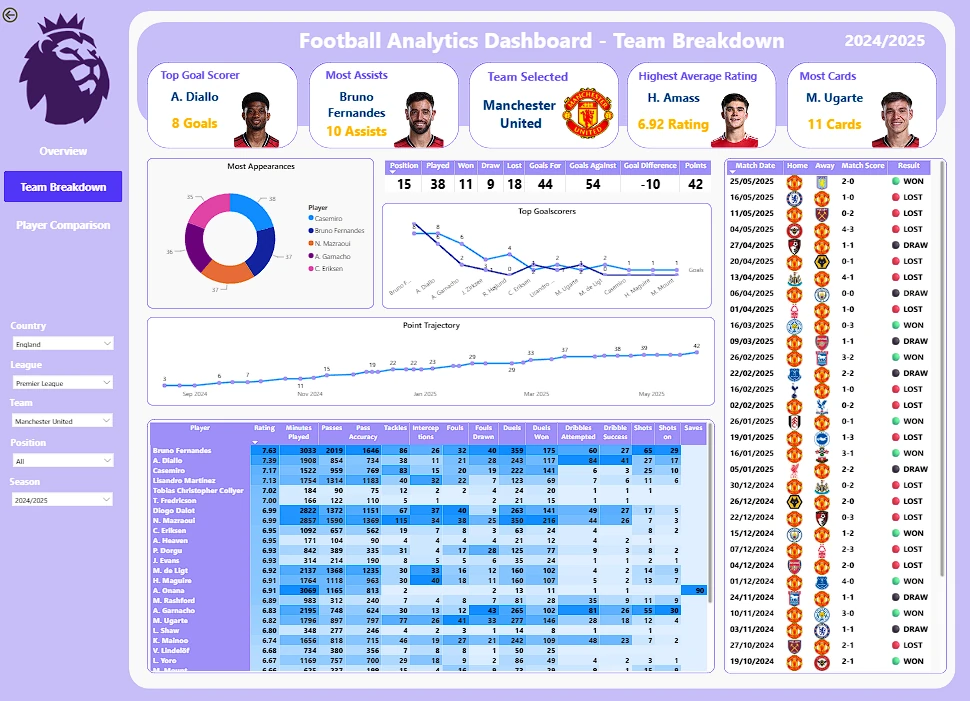
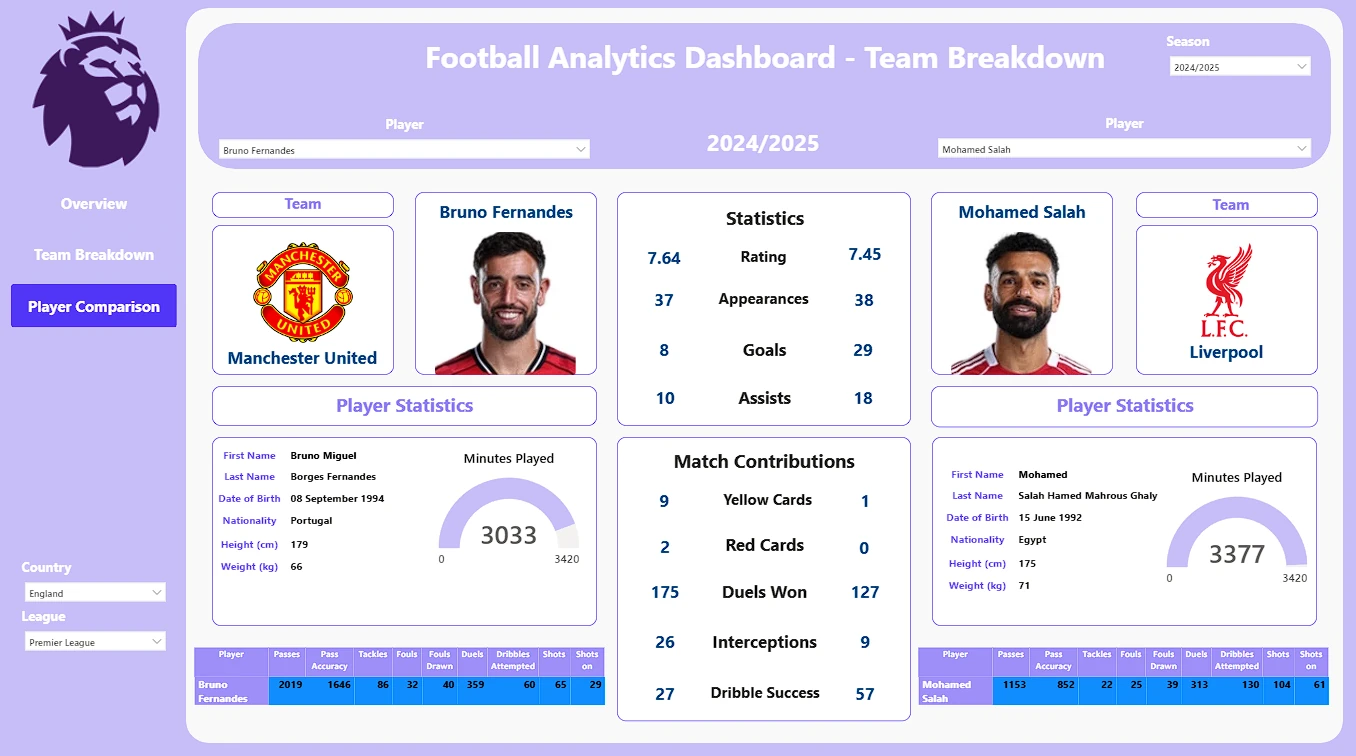
From league overview to player comparison
The report moves from competition-level performance into individual team and player analysis. Select a dashboard view to open the screenshot at full size.
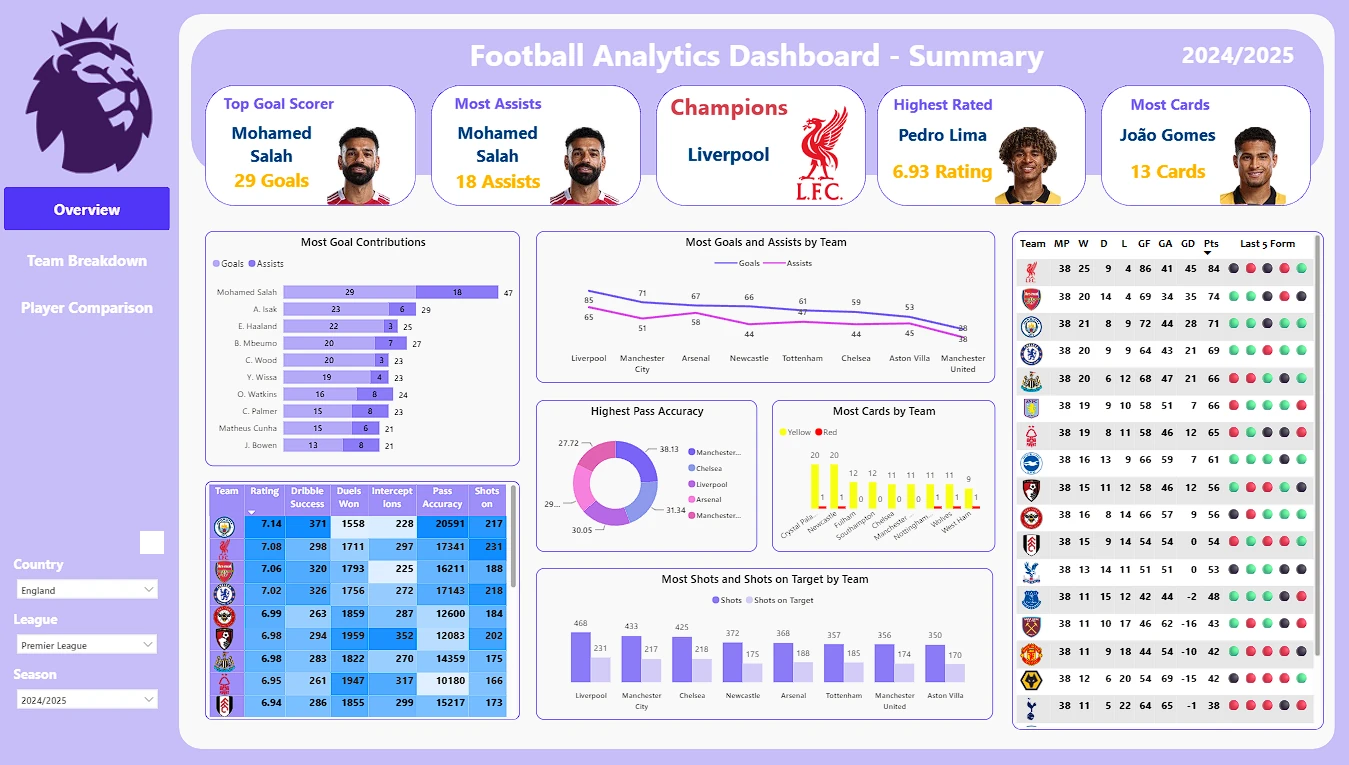 OverviewStandings, scorers, assists, ratings and team metrics
Data model
The SQL model separates data by grain so league standings, matches and player performance can coexist cleanly in the same reporting model.
What I learned
This project gave me a much better understanding of how source-system limits, data grain, staging, incremental updates and automation affect the design of a real data pipeline rather than a one-off dashboard.